Integrate in five minutes
OpenAI, Anthropic Messages, Responses and Gemini compatible endpoints. Check model, protocol and tool support before integrating.
Send your first request
Create an API key in the dashboard, then run:
Create an API key in the dashboard, replace the placeholder below with your key, and run this in the same terminal as the examples. The curl, SDK and client configurations read this environment variable.
export KIMISEEK_API_KEY="ks-your-key"curl https://api.kimiseek.app/v1/chat/completions \
-H "Authorization: Bearer ${KIMISEEK_API_KEY:?Set KIMISEEK_API_KEY in this terminal first.}" \
-H "Content-Type: application/json" \
-d '{
"model": "deepseek-v4-pro-0813",
"max_completion_tokens": 1024,
"messages": [
{
"role": "user",
"content": "Hello from KimiSeek"
}
]
}'Authentication
Use your KimiSeek API key in Authorization: Bearer for OpenAI endpoints; Anthropic Messages also accepts x-api-key. Keys start with ks- and can be copied from the dashboard key list.
Never expose an API key in browser code or a public repository.
Supported models and pricing
Copy a model ID from this table into the model field. Rates are KimiSeek's current selling prices for real-time requests.
| Model and API ID | Pricing tier | Input | Cached input | Output | Context |
|---|---|---|---|---|---|
DeepSeek V4 Pro 0813deepseek-v4-pro-0813Alias: deepseek-v4-proCurrently available protocols: OpenAI Chat Completions · /v1/chat/completions · Responses /v1/responses; Anthropic Messages · /v1/messages; Gemini · /v1beta/models/{model}:generateContent. | Peak (01:00–04:00, 06:00–10:00 UTC (Beijing time 09:00–12:00, 14:00–18:00)) · Time bands from 2026-08-20 13:03:49.577 UTC; peak rates apply all day before then | ¥4.5 | ¥0.15 | ¥13.5 | 1M |
| Off-peak (outside 01:00–04:00, 06:00–10:00 UTC (Beijing time 09:00–12:00, 14:00–18:00)) · Time bands from 2026-08-20 13:03:49.577 UTC; peak rates apply all day before then | ¥2.25 | ¥0.075 | ¥6.75 | ||
DeepSeek V4.1 Flashdeepseek-v4.1-flashAlias: deepseek-flashCurrently available protocols: OpenAI Chat Completions · /v1/chat/completions · Responses /v1/responses; Anthropic Messages · /v1/messages; Gemini · /v1beta/models/{model}:generateContent. | Off-peak (outside 01:00–04:00, 06:00–10:00 UTC (Beijing time 09:00–12:00, 14:00–18:00)) · Time bands from 2026-08-16 16:00:00.000 UTC; peak rates apply all day before then | ¥0.5 | ¥0.01 | ¥2 | 1M |
| Peak (01:00–04:00, 06:00–10:00 UTC (Beijing time 09:00–12:00, 14:00–18:00)) · Time bands from 2026-08-16 16:00:00.000 UTC; peak rates apply all day before then | ¥1 | ¥0.02 | ¥4 | ||
Qwen4 Maxqwen4-maxCurrently available protocols: OpenAI Chat Completions · /v1/chat/completions · Responses /v1/responses; Anthropic Messages · /v1/messages; Gemini · /v1beta/models/{model}:generateContent. | Standard | ¥8.5 | ¥0.425 | ¥25.5 | 1M |
GLM-5.3 Flashglm-5.3-flashCurrently available protocols: OpenAI Chat Completions · /v1/chat/completions · Responses /v1/responses; Anthropic Messages · /v1/messages; Gemini · /v1beta/models/{model}:generateContent. | Standard | ¥0.4 | ¥0.115 | ¥1.4 | 1M |
Qwen3.8 Maxqwen3.8-maxCurrently available protocols: OpenAI Chat Completions · /v1/chat/completions · Responses /v1/responses; Anthropic Messages · /v1/messages; Gemini · /v1beta/models/{model}:generateContent. | Standard | ¥6 | ¥0.75 | ¥18 | 991K |
GLM-5.3glm-5.3Alias: GLM-5.3Currently available protocols: OpenAI Chat Completions · /v1/chat/completions · Responses /v1/responses; Anthropic Messages · /v1/messages; Gemini · /v1beta/models/{model}:generateContent. | Standard | ¥4 | ¥1 | ¥14 | 1.024M |
Kimi K3kimi/kimi-k3Alias: kimi-k3Currently available protocols: OpenAI Chat Completions · /v1/chat/completions · Responses /v1/responses; Anthropic Messages · /v1/messages; Gemini · /v1beta/models/{model}:generateContent. | Standard | ¥16 | ¥1.6 | ¥80 | 1.048576M |
Kimi K3.1 Pro Highspeedkimi/kimi-k3.1-pro-highspeedAlias: kimi-k3.1Alias: kimi-k3.1-proCurrently available protocols: OpenAI Chat Completions · /v1/chat/completions · Responses /v1/responses; Anthropic Messages · /v1/messages; Gemini · /v1beta/models/{model}:generateContent. | Standard | ¥13 | ¥0.65 | ¥68 | 1.048576M |
Qwen3.8 Flashqwen3.8-flashCurrently available protocols: OpenAI Chat Completions · /v1/chat/completions · Responses /v1/responses; Anthropic Messages · /v1/messages; Gemini · /v1beta/models/{model}:generateContent. | Standard | ¥0.4 | ¥0.05 | ¥1.35 | 1M |
Qwen3.8 27Bqwen3.8-27bCurrently available protocols: OpenAI Chat Completions · /v1/chat/completions · Responses /v1/responses; Anthropic Messages · /v1/messages; Gemini · /v1beta/models/{model}:generateContent. | Standard | ¥0.9 | ¥0.18 | ¥3.6 | 1M |
Qwen3.8 2.4T A95Bqwen3.8-2.4t-a95bCurrently available protocols: OpenAI Chat Completions · /v1/chat/completions · Responses /v1/responses; Anthropic Messages · /v1/messages; Gemini · /v1beta/models/{model}:generateContent. | Standard | ¥9.6 | ¥1.2 | ¥28.8 | 1M |
Qwen3.7 Maxqwen3.7-maxCurrently available protocols: OpenAI Chat Completions · /v1/chat/completions · Responses /v1/responses; Anthropic Messages · /v1/messages; Gemini · /v1beta/models/{model}:generateContent. | Standard | ¥6 | ¥1.2 | ¥18 | 991K |
Qwen3.6 Plusqwen3.6-plusCurrently available protocols: OpenAI Chat Completions · /v1/chat/completions · Responses /v1/responses; Anthropic Messages · /v1/messages; Gemini · /v1beta/models/{model}:generateContent. | Input ≤ 256,000 tokens | ¥1.6 | Input rate | ¥9.6 | 1M |
| Input ≥ 256,001 tokens | ¥6.4 | Input rate | ¥38.4 | ||
Qwen3.7 Plusqwen3.7-plusCurrently available protocols: OpenAI Chat Completions · /v1/chat/completions · Responses /v1/responses; Anthropic Messages · /v1/messages; Gemini · /v1beta/models/{model}:generateContent. | Input ≤ 256,000 tokens | ¥1.6 | ¥0.32 | ¥6.4 | 1M |
| Input ≥ 256,001 tokens | ¥4.8 | ¥0.96 | ¥19.2 | ||
DeepSeek V4.1 Flash 1017deepseek-v4.1-flash-1017Currently available protocols: OpenAI Chat Completions · /v1/chat/completions · Responses /v1/responses; Anthropic Messages · /v1/messages; Gemini · /v1beta/models/{model}:generateContent. | Off-peak (outside 01:00–04:00, 06:00–10:00 UTC (Beijing time 09:00–12:00, 14:00–18:00)) · Time bands from 2026-10-18 23:42:09.074 UTC; peak rates apply all day before then | ¥0.5 | ¥0.05 | ¥2 | 1.024M |
| Peak (01:00–04:00, 06:00–10:00 UTC (Beijing time 09:00–12:00, 14:00–18:00)) · Time bands from 2026-10-18 23:42:09.074 UTC; peak rates apply all day before then | ¥1 | ¥0.1 | ¥4 |
Image model pricing
Rates are CNY per image, using each model’s current discount. Reference and generated images are charged separately. See the table for resolution tiers and prompt-enhancement rates; the regular output rate applies when no enhancement rate is listed.
| Image model | Reference / image | Output / image | Enhanced output / image |
|---|---|---|---|
Qwen Image 3.0 Proqwen-image-3.0-proCurrently available protocols: OpenAI Images · /v1/images/generations. | ¥0.016 | 262,144–2,250,000 pixels¥0.22,250,001–4,194,304 pixels¥0.4 | — |
Qwen Image 3.0qwen-image-3.0Currently available protocols: OpenAI Images · /v1/images/generations. | ¥0.016 | 262,144–4,194,304 pixels¥0.144 | — |
Wan 2.7 Image Prowan2.7-image-proCurrently available protocols: OpenAI Images · /v1/images/generations. | ¥0 | 589,824–16,777,216 pixels¥0.4 | — |
Wan 2.7 Imagewan2.7-imageCurrently available protocols: OpenAI Images · /v1/images/generations. | ¥0 | 589,824–4,194,304 pixels¥0.16 | — |
Z-Image Turboz-image-turboCurrently available protocols: OpenAI Images · /v1/images/generations. | ¥0 | 262,144–4,194,304 pixels¥0.08 | 262,144–4,194,304 pixels¥0.16 |
Text model prices are in CNY per 1M tokens. The applicable tier depends on each model’s input range, request start time and effective-date conditions. View full pricing and explicit-cache details
A public machine-readable catalog is also available, with no API key required, at: GET https://api.kimiseek.app/v1/models
API examples
Examples below use currently configured models and protocols. Use your own KimiSeek API key.
curl https://api.kimiseek.app/v1/chat/completions \
  -H "Authorization: Bearer ${KIMISEEK_API_KEY:?Set KIMISEEK_API_KEY in this terminal first.}" \
  -H "Content-Type: application/json" \
  -d '{
  "model": "deepseek-v4-pro-0813",
  "max_completion_tokens": 1024,
  "messages": [
    {
      "role": "user",
      "content": "Hello from KimiSeek"
    }
  ]
}'curl https://api.kimiseek.app/v1/messages \
-H "x-api-key: ${KIMISEEK_API_KEY:?Set KIMISEEK_API_KEY in this terminal first.}" \
-H "anthropic-version: 2023-06-01" \
-H "Content-Type: application/json" \
-d '{
"model": "deepseek-v4-pro-0813",
"max_tokens": 1024,
"messages": [
{
"role": "user",
"content": "Hello from KimiSeek"
}
]
}'curl https://api.kimiseek.app/v1/responses \
-H "Authorization: Bearer ${KIMISEEK_API_KEY:?Set KIMISEEK_API_KEY in this terminal first.}" \
-H "Content-Type: application/json" \
-d '{
"model": "deepseek-v4-pro-0813",
"input": "Hello from KimiSeek",
"max_output_tokens": 1024
}'curl https://api.kimiseek.app/v1beta/models/deepseek-v4-pro-0813:generateContent \
-H "Authorization: Bearer ${KIMISEEK_API_KEY:?Set KIMISEEK_API_KEY in this terminal first.}" \
-H "Content-Type: application/json" \
-d '{
"contents": [
{
"role": "user",
"parts": [
{
"text": "Hello from KimiSeek"
}
]
}
],
"generationConfig": {
"maxOutputTokens": 1024
}
}'Choosing a model tier? Compare Kimi K3, Qwen3.8 Flash and GLM-5.3 Flash with live catalog prices →
Image generation API
Call image models with /v1/images/generations. Set image to HTTPS references or image data URLs when editing.
curl https://api.kimiseek.app/v1/images/generations \
  -H "Authorization: Bearer ${KIMISEEK_API_KEY:?Set KIMISEEK_API_KEY in this terminal first.}" \
  -H "Content-Type: application/json" \
  -d '{
  "model": "qwen-image-3.0-pro",
  "prompt": "A red panda reading under a cedar tree",
  "size": "1024x1024",
  "n": 1,
  "prompt_extend": false
}'
Use the official OpenAI SDK
Change only model to switch providers. Each request is routed to the upstream configured for that model.
import OpenAI from "openai";

const apiKey = process.env.KIMISEEK_API_KEY;
if (!apiKey) throw new Error("Set KIMISEEK_API_KEY in this terminal first.");

const client = new OpenAI({
  apiKey,
  baseURL: "https://api.kimiseek.app/v1",
});

const reply = await client.chat.completions.create({
  model: "deepseek-v4-pro-0813",
  messages: [{ role: "user", content: "Hello from KimiSeek!" }],
  max_completion_tokens: 1024,
});Claude Code and Codex
Configure with CC Switch
Use the CC Switch interface to add KimiSeek as a provider for Codex and Claude Code separately.
- Create or copy a KimiSeek API key in the dashboard first. Open API key management
- Open CC Switch, select Codex or Claude Code, and add a custom provider, or edit an existing one.
- Enter the provider details below. Website and notes are optional and can be left blank.
- Provider name
kimiseek- API Key
- Your own KimiSeek API key (starting with ks-)
- Default model
- The screenshots use glm-5.3-flash. You can also copy an available model ID from the catalog above.
- Enter the API request address (Base URL) shown below for your client. Leave the Full URL switch off.
- Click Save, enable KimiSeek in that client's provider list, then restart the client. Configure and enable each client separately if you use both.
Codex
Default model: deepseek-v4-pro-0813
https://api.kimiseek.app/v1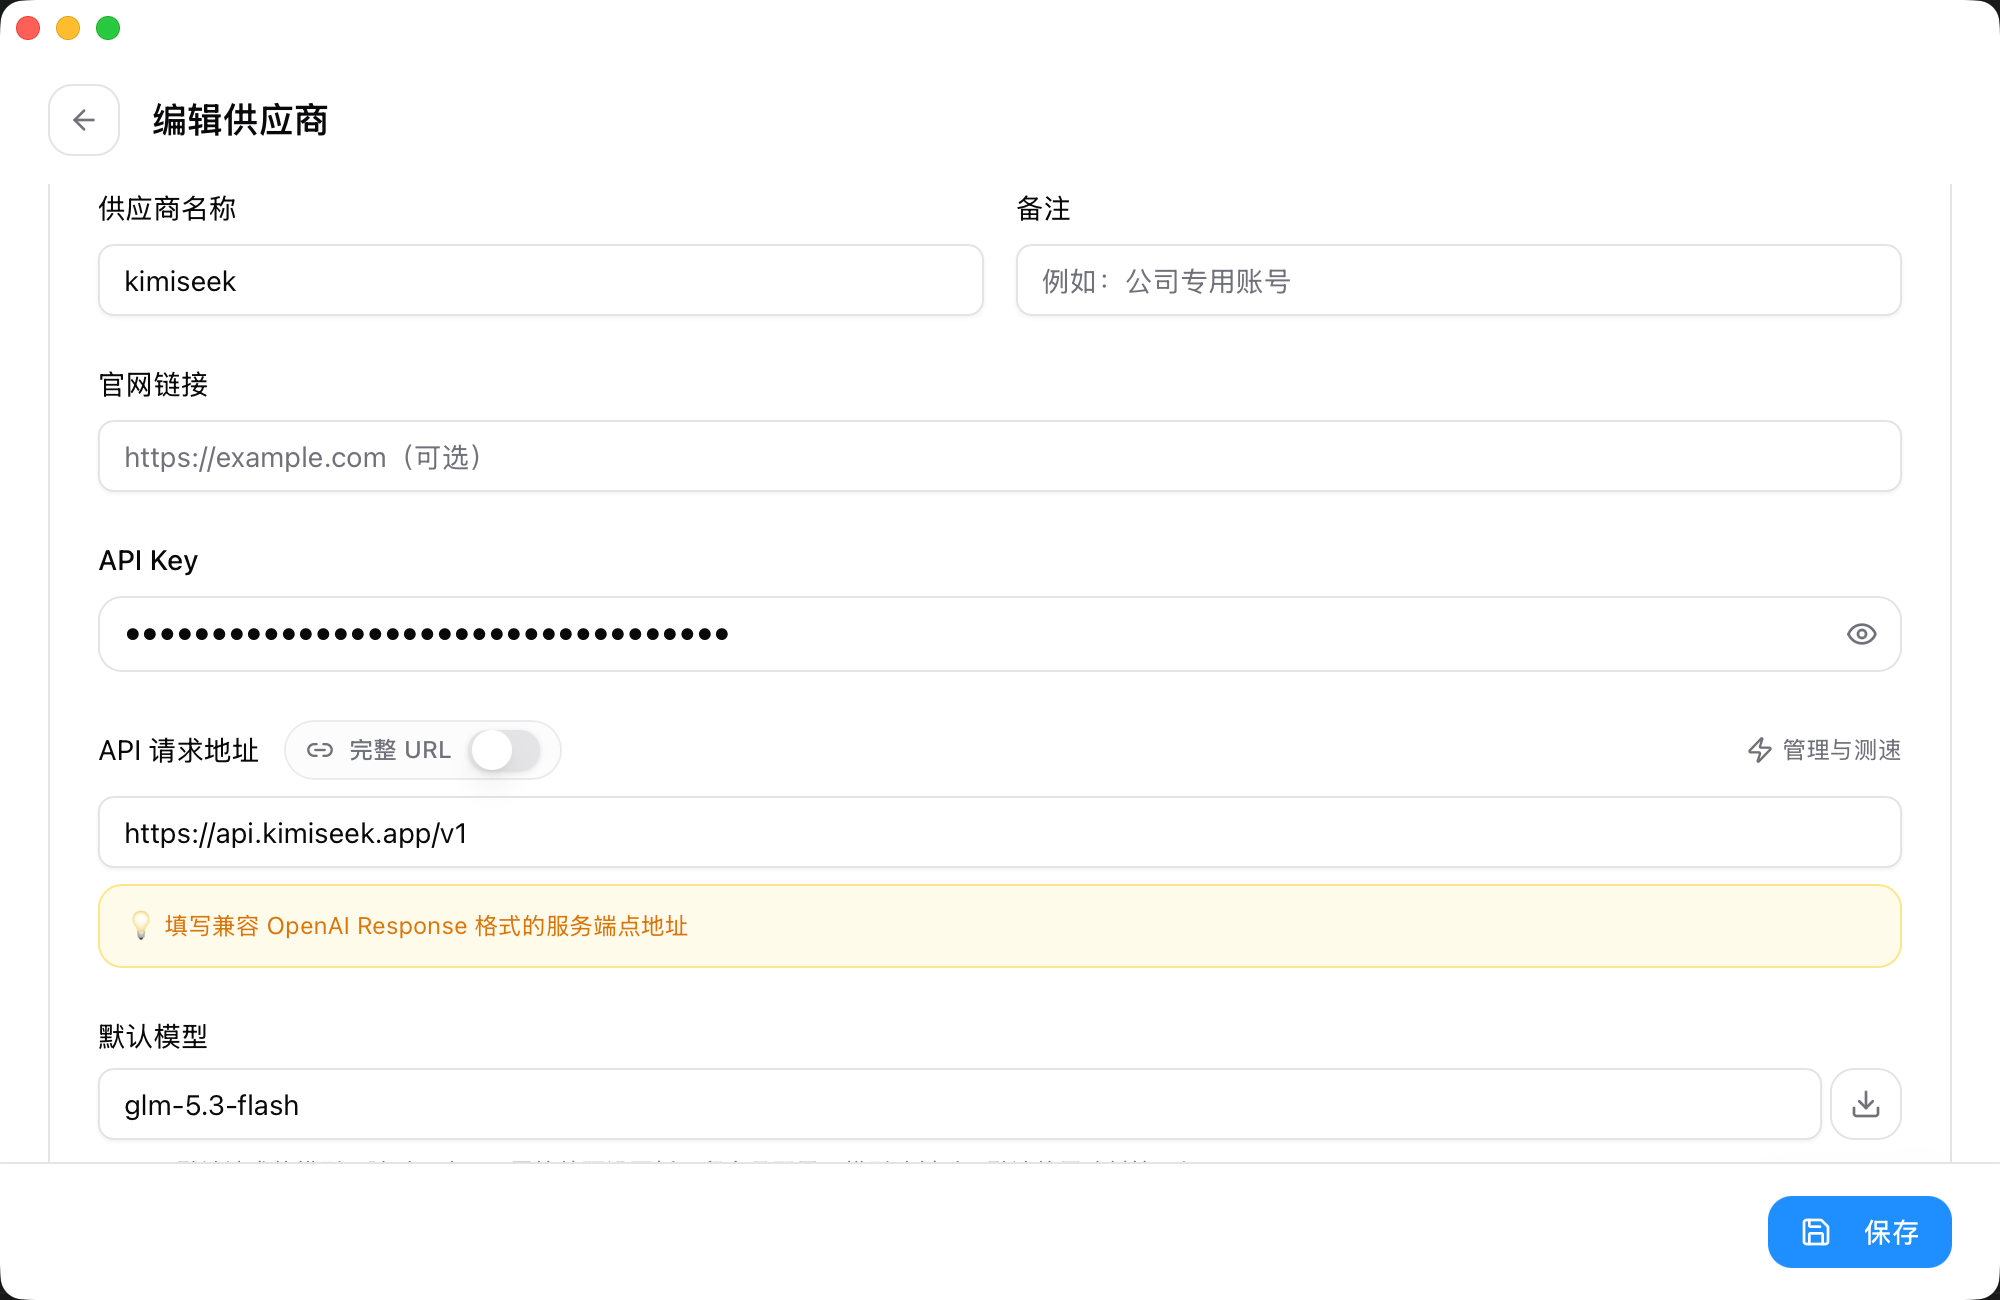
Claude Code
Default model: deepseek-v4.1-flash
https://api.kimiseek.app/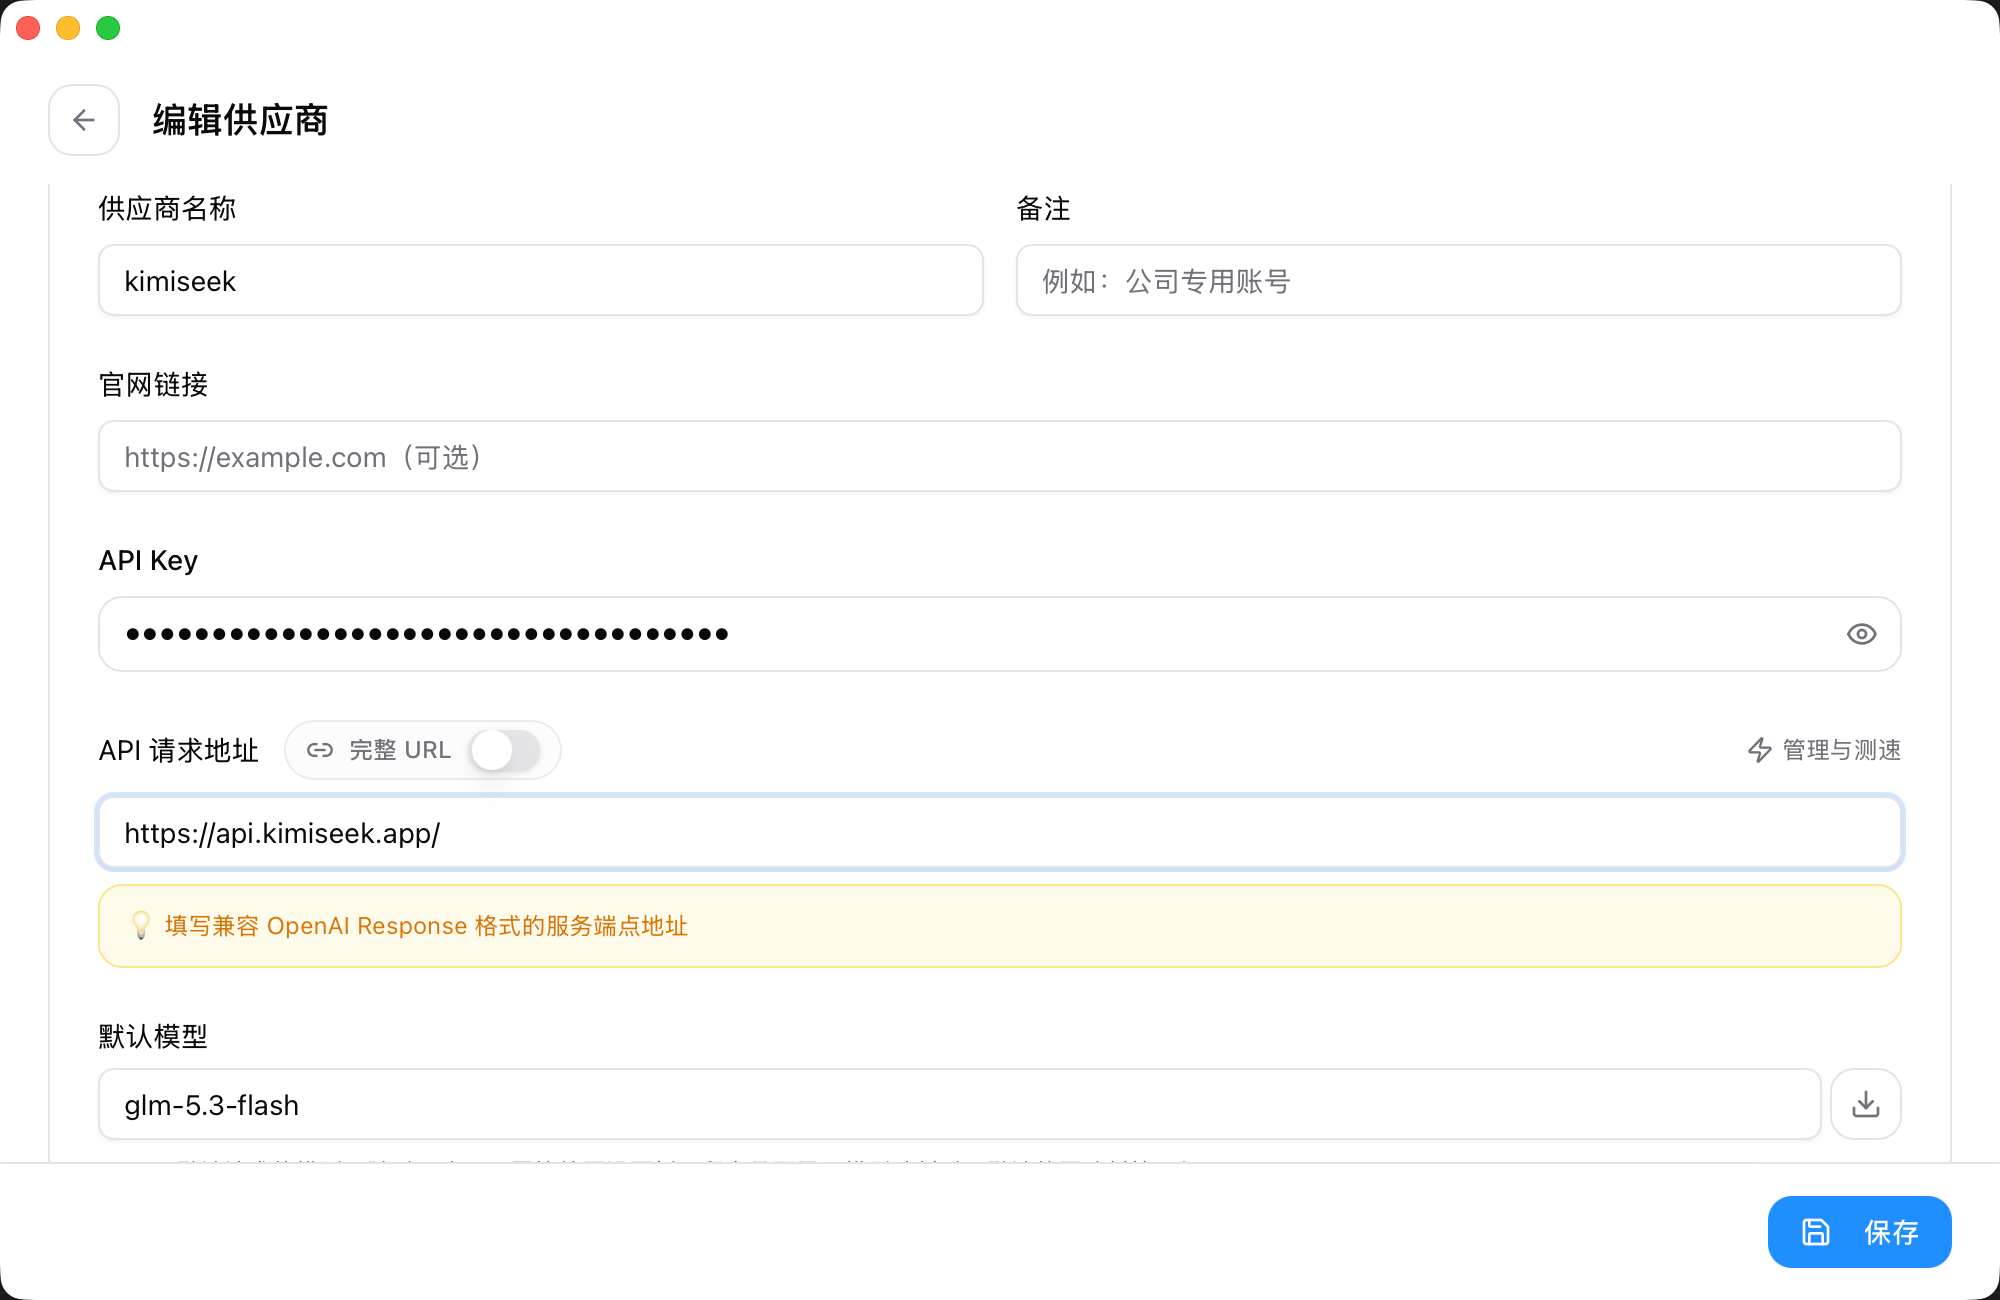
Claude Code uses the Anthropic Messages compatibility endpoint.
export ANTHROPIC_BASE_URL="https://api.kimiseek.app"
export ANTHROPIC_MODEL='deepseek-v4.1-flash'
export ANTHROPIC_AUTH_TOKEN="${KIMISEEK_API_KEY:?Set KIMISEEK_API_KEY in this terminal first.}" && claude
Codex uses the Responses API and reads KIMISEEK_API_KEY from the environment.
Responses client tools currently support flat functions only; custom, namespace and hosted tools are dropped and not executed. Tool support: Codex · Responses
model = "deepseek-v4-pro-0813"
model_provider = "kimiseek"

[model_providers.kimiseek]
name = "KimiSeek"
base_url = "https://api.kimiseek.app/v1"
env_key = "KIMISEEK_API_KEY"
wire_api = "responses"generateContent and streamGenerateContent accept parts[].text only; pass the key with x-goog-api-key. Images, files, tools, toolConfig and function-call history are unsupported and return HTTP 400 before forwarding or billing. Use another compatible endpoint with a tool-capable model for tools. Only text output is supported; audio or image generation also returns HTTP 400 before forwarding or billing.
Streaming
Set stream: true for standard SSE. Generated usage is settled when the stream completes or is interrupted.
Error codes
400Invalid request or model name401Invalid API key or exhausted quota402Insufficient CNY balance503Model channel unavailableCNY billing
Input, cached input and output tokens are multiplied by their rates and settled entirely in CNY.
Each request reserves its estimated cost (at least ¥0.10) from the available account and key budgets. Running requests and pending charges also use that budget. If it is insufficient, wait for requests to finish or lower the output or separate thinking budget.
Each account can run up to 4 model requests at once. A reservation is not a charge; actual usage determines the final bill. Usage above the estimate is still charged and may make the balance negative. Top-ups first cover any amount owed. Without an output limit, the model maximum is reserved. Separate thinking budgets are added; unspecified thinking budgets conservatively use the context limit.