JD Logistics says ChaoNao 3.0 cuts route planning to seconds: five industrial models, but no public weights or API mentioned
According to a November 6, 2026 article on InfoQ China, JD Logistics has iterated its ChaoNao large model to version 3.0 and claims it has cut the time to solve optimal route planning for hundreds of millions of parcels from minutes to seconds. The system consists of five supply-chain-native models — PreX, OptiX, OmniX, GeoX and EmbodiedX — and covers more than 3,600 warehouses and over 600,000 employees, with an automated vehicle dispatch rate of 86%. The article does not mention public weights, an open-source license or any interface third parties can call directly.
What changed
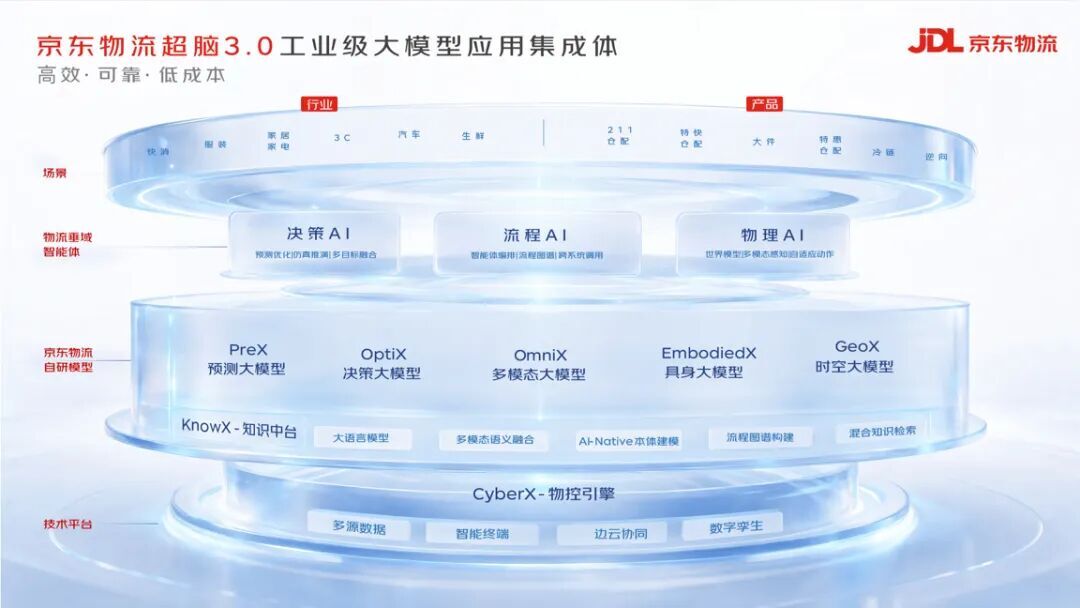
According to an article published by InfoQ China on November 6, 2026, JD Logistics has iterated its ChaoNao large model to version 3.0, which the article describes as an industrial-grade large-model application integration in which AI directs the entire process from warehousing to delivery. Compared with 2.0, the article says 3.0 operates more efficiently, has greater system resilience and lower operating costs, and has cut the solving time for end-to-end optimal route planning of hundreds of millions of parcels from minutes to seconds. The system consists of five supply-chain-native models: PreX predicts changes in demand and supply from multidimensional dynamic data; OptiX combines operations research optimization, reinforcement learning and generative model capabilities to solve global plans under constraints such as warehouse network, inventory, transport, personnel and equipment; OmniX uniformly understands images, video, space and objects; GeoX places addresses, locations, routes and time in a unified spatiotemporal coordinate system; and EmbodiedX converts perception and decisions into actions robots can execute. The article describes this setup as a trinity of decision AI, process AI and physical AI. The decision layer uniformly models orders, inventory, warehouse networks, vehicles, road conditions, weather, as well as image, video and location information. The process layer connects data across warehousing, transport, sorting and delivery systems, unifies definitions of people, goods, vehicles, warehouses, orders and equipment, then breaks decisions into executable tasks that are dispatched, tracked and handled when exceptions occur. The physical layer is driven by the CyberX control engine, which operates the "Zhilang" robots, the "Yilang" sorting robotic arms and the "Dulang" unmanned delivery vehicles to execute tasks and feed results back, forming a closed loop of perception, prediction, decision, execution and feedback. Other figures given in the article include: coverage of more than 3,600 warehouses and over 600,000 employees; an automated vehicle dispatch rate of 86%; a 13.8% productivity improvement for warehouse staff; the merchant-facing "Jinghui" end-to-end supply chain service, which claims next-day delivery fulfillment averaging above 80% and can automatically provide replenishment suggestions and execute transfers; "Yilang" already running 24 hours a day in multiple logistics parks, having cumulatively validated the grabbing and palletizing of tens of millions of real parcels; and "Dulang" piloted in multiple locations across China and in Saudi Arabia. The article also says these capabilities are being opened up to manufacturing, retail and other industries.
What it means for developers
First, separate the verifiable from the unverifiable. All the figures above come from JD Logistics' own account. The article gives no model parameter count, training data scale, benchmark methodology, inference hardware or statistical time window, and it does not mention open weights, an open-source license, a model card or a public API for third parties. For developers, this reads more like an operating summary of a proprietary system than a model that can be downloaded, hosted or called per token. The metrics also leave gaps. "Seconds" does not specify whether it is an average or a tail latency, nor the order volume, solving time limit or hardware on which it was measured; the 86% automated vehicle dispatch rate does not make clear whether the denominator is all vehicles or vehicles meeting certain conditions; and the 13.8% productivity improvement for staff has no control group or statistical period. Such operational figures are better treated as vendor claims awaiting verification than as performance expectations that can be extrapolated directly to one's own business. What is genuinely transferable is the architectural division of labor rather than the specific numbers: splitting prediction, constraint solving, multimodal perception, spatiotemporal cognition and physical control into separate modules, and using a process layer to align entity definitions across systems before orchestration. This order addresses the problem of decisions that can be computed but cannot be put into practice. The cost is equally clear: an extra layer of semantic unification means an extra layer of mapping objects and failure points that need long-term maintenance, and it only pays off when data really is scattered across heterogeneous systems. Another ambiguity is "opening up to industries." The article does not say whether this is delivered as a product, an SDK, an API or project-based work, nor does it list access conditions or billing. The clearest external offering described is the merchant-facing "Jinghui," but that is a supply chain service rather than a model interface; adopting it means handing over order, inventory, warehouse network and fulfillment data, and validating it item by item against the merchant's own scenarios.
Integration and evaluation
The following is conditional analysis and advice, not facts stated in the article. Teams planning to put large models into scheduling or orchestration pipelines can start with small-scale controlled experiments based on two practices described in the article. First, process AI unifies definitions of people, goods, vehicles, warehouses, orders and equipment before orchestrating tasks, and this is worth validating separately. The choice to make is whether to add a unified semantic layer of entities and rules in front of your agent orchestration layer. The precondition is that data really is scattered across multiple systems and the same business object is defined inconsistently at different stages; if there is only one data source, this layer would only add latency and maintenance surface. A measurable acceptance criterion is to run the same batch of historical work orders through two pipelines — "unify definitions first" and "let the model decompose end to end directly" — and compare field mapping errors, retry rate, manual takeover rate and end-to-end latency, requiring the first two to fall without a significant rise in latency. Second, decision AI puts prediction and constraint solving into the same rolling loop and claims to update decisions within seconds when orders, roads or capacity change. The choice to make is whether scheduling tasks should have a generative model output the final plan directly, or whether prediction, solving and execution feedback should be split into three stages evaluated separately. The precondition is that your problem has hard constraints (time, cost, capacity) and high error costs; pure ranking or recommendation tasks can keep a single-model approach. A measurable criterion is to replay historical orders and compare constraint violation rates, the cost gap against the existing rule-based baseline, and recovery time after injecting disturbances. Third, the physical AI part cannot be reproduced locally and can only be validated through pilot or procurement processes. To evaluate robotic arm or unmanned vehicle solutions, first define the range of parcel form diversity at the site, then require observable metrics such as continuous operating hours, grab success rate, damage rate and frequency of manual intervention, rather than accepting descriptions like "running in normal operation." One more low-cost step applies to any similar account: write directly into the evaluation form the definitions you need the other party to provide, including latency percentiles, problem scale, hardware configuration, statistical window and control group setup. Without these, the other party's numbers cannot be converted into your own capacity planning.
Limits and open questions
All performance and efficiency figures in the article are provided by JD Logistics alone and lack third-party reproduction; they should not be treated as an extrapolatable capability baseline. The article only explains the division of responsibilities among the five models and gives no information needed for model selection, such as parameter scale, license terms, whether weights are released or inference cost. The concrete form, access thresholds and billing of "opening up to manufacturing, retail and other industries" are not explained, and the actual scope of availability of "Jinghui" also needs to be confirmed with JD Logistics. It should be clear that JD Logistics' ChaoNao large model 3.0 is not currently in KimiSeek's model catalog; this site has no corresponding entry for it, and this article does not treat it as a model callable on this site. The external services mentioned and their availability, specifications and billing are subject to JD Logistics' own statements. If this system later publishes an API or weights, whether it is worth integrating should still be evaluated separately against the measurable criteria above.
Illustrations from the original report